Why your Time to First Byte is slow and what to do about it
TTFB is not a single bug. It is the visible delay caused by DNS, connection setup, CDN routing, server work, cache misses, and sometimes one slow database query.
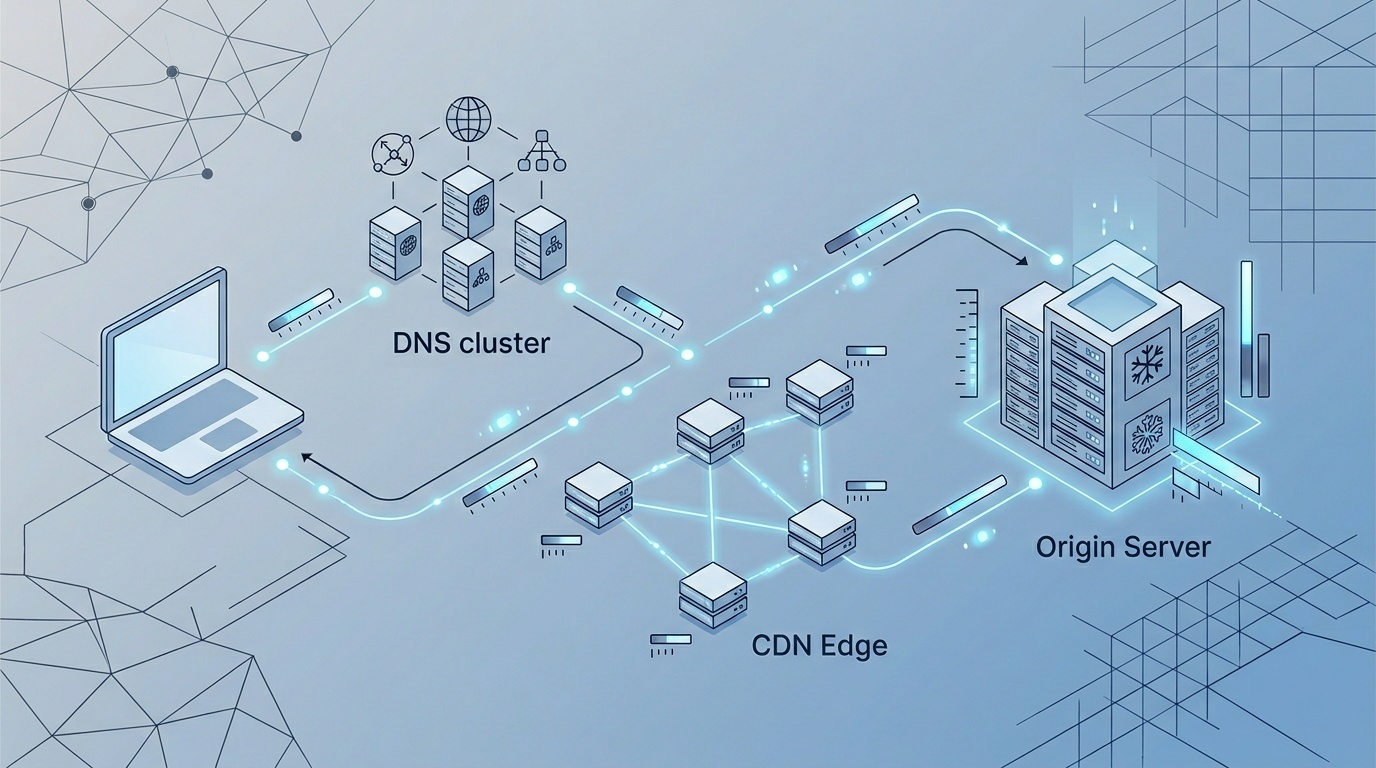
Table of contents
- Start with what TTFB actually measures
- What counts as a slow TTFB?
- Measure it in more than one place
- 1. Browser developer tools
- 2. Synthetic tests from multiple regions
- 3. Real user monitoring or server logs
- The usual causes of slow TTFB
- Your HTML is not being cached
- Your CDN is only caching assets
- Your server is doing too much before responding
- Database queries are slow or unpredictable
- Your application has cold starts
- Redirects are wasting the first request
- A practical debugging sequence
- Step 1: Test the main document, not just the whole page
- Step 2: Compare regions
- Step 3: Inspect response headers
- Step 4: Check origin timing
- Step 5: Fix the largest confirmed delay
- Fixes that usually work
- Cache public HTML at the edge
- Move non-critical work out of the request path
- Reduce backend dependency chains
- Put compute closer to users
- Keep redirects boring
- What not to do
- The calm version of the plan
Start with what TTFB actually measures
Time to First Byte, usually shortened to TTFB, is the time between the browser requesting a resource and receiving the first byte of the response.
That sounds like a server metric, but it is not only a server metric. TTFB includes several steps:
- DNS lookup, if the hostname is not already resolved
- TCP connection setup
- TLS negotiation for HTTPS
- Request travel time to the server or CDN edge
- Queueing and processing on the server
- Response travel time back to the browser
So a high TTFB can mean your backend is slow. It can also mean the user is far from your origin, your CDN is misconfigured, your cache is constantly missing, or your server is spending too long deciding what to send.
This matters because TTFB sits near the beginning of the loading chain. If the HTML document arrives late, the browser discovers CSS, JavaScript, fonts, and images late too. You can have excellent front-end optimization and still feel slow if the first document response takes 1.5 seconds.
What counts as a slow TTFB?
There is no universal number that fits every site, region, and architecture. Still, practical thresholds help.
Google’s web.dev guidance classifies a good TTFB as under 800 ms, with 800–1800 ms needing improvement and above 1800 ms considered poor. For a well-cached marketing page served near the user, you can often do much better than that. For a complex authenticated dashboard doing dynamic work, the acceptable number may be higher, but it should still be explainable.
The important habit is to segment the number. A global average TTFB of 900 ms may hide a 150 ms response for users near your CDN edge and a 2200 ms response for users in another region. Likewise, your homepage may be fine while search, category, or logged-in pages are quietly painful.
Measure it in more than one place
Do not diagnose TTFB from a single Lighthouse run. Lighthouse is useful, but it is one test from one environment. If you are new to interpreting it, start with a calm reading of how to read a Lighthouse report without panicking — the main lesson is to separate lab signals from field reality.
For TTFB, you want at least three views:
1. Browser developer tools
Open the Network panel, reload with cache disabled, and inspect the main document request. The timing breakdown shows DNS, connection, TLS, waiting, and download phases. The “waiting” phase is often what people mean by backend time, though it can include upstream latency.
2. Synthetic tests from multiple regions
Run tests from locations close to and far from your users. If TTFB is low in one region and high in another, suspect geography, CDN routing, origin placement, or cache coverage before rewriting application code.
3. Real user monitoring or server logs
Field data tells you what real users experience across devices, networks, and sessions. Server logs can tell you whether the origin generated a response quickly. The difference between client-observed TTFB and origin processing time is often where CDN and network issues appear.
The usual causes of slow TTFB
Your HTML is not being cached
This is the most common issue on content sites and ecommerce sites. Static assets are cached aggressively, but the HTML document — the thing the browser needs first — is generated on every request.
Sometimes that is necessary. Often it is not.
If a public page changes a few times per day, it probably should not require a fresh database render for every anonymous visitor. Use full-page caching, edge caching, static generation, or stale-while-revalidate patterns where appropriate.
Check response headers for signals like Cache-Control, CDN-Cache-Status, Age, Vary, and Set-Cookie. A page that sends a unique cookie to every visitor may accidentally make itself uncacheable. If you need a practical way to reason about this layer, the same debugging habits in our guide to redirects and HTTP headers in production apply directly to TTFB work.
Your CDN is only caching assets
Many teams add a CDN and assume the performance job is done. But if the CDN only serves images, CSS, and JavaScript, the first HTML request may still travel all the way to a single origin server.
That can be fine for a local business site with local users. It is not fine for an international audience. The farther the user is from the origin, the more latency you pay before backend work even starts.
Good CDN configuration for TTFB usually means:
- Cache public HTML where safe
- Respect intentional bypass rules for authenticated or personalized pages
- Avoid unnecessary
Varyheaders that split the cache too finely - Use cache purging or revalidation instead of disabling cache entirely
- Confirm that edge locations are actually serving hits, not forwarding every request
A CDN is not magic. It is a cache and routing layer. Treat it like one.
Your server is doing too much before responding
A slow backend path can come from many small delays: database queries, API calls, template rendering, feature flag checks, authentication, personalization, logging, and cold starts.
The worst pattern is serial dependency work. For example:
- Fetch page data
- Then fetch related products
- Then fetch pricing
- Then call a recommendations service
- Then render HTML
If each step waits for the previous one, TTFB grows quickly. Parallelize independent work, remove non-critical calls from the first response, and cache expensive results.
A useful rule: if the user cannot see or use the result immediately, it probably should not block the first byte.
Database queries are slow or unpredictable
Databases often cause TTFB problems because they behave well in development and poorly under real traffic. Missing indexes, large joins, N+1 queries, lock contention, and oversized result sets all show up as “the server is slow”.
Do not guess here. Capture query timings for slow requests. Look at p95 and p99, not just averages. One page that usually responds in 120 ms but occasionally blocks for 4 seconds will still create a bad user experience.
Common fixes include:
- Adding or correcting indexes
- Removing N+1 query patterns
- Caching read-heavy data
- Paginating large queries
- Moving reporting or analytics queries away from request time
- Setting sensible timeouts for downstream calls
Your application has cold starts
Serverless and containerized platforms can be excellent, but cold starts can hurt TTFB when traffic is bursty or regions are under-provisioned.
If your first request after idle time is much slower than later requests, investigate cold starts. You may need provisioned concurrency, smaller bundles, fewer startup dependencies, warmer functions, or a different deployment shape for latency-sensitive routes.
This is not an argument against serverless. It is an argument against pretending the runtime model is invisible.
Redirects are wasting the first request
A redirect adds another request-response cycle before the browser receives the final document. One redirect from http:// to https:// may be unavoidable for old links, but chains are wasteful.
Common chains include:
http://example.com→https://example.com→https://www.example.com- trailing slash normalization after protocol normalization
- geo or language redirects before cache lookup
- legacy campaign links that hop through several URLs
Fix the source links where possible, collapse redirect rules, and make canonical URLs direct. Redirect time is not always reported as TTFB for the final request, but the user still pays for it.
A practical debugging sequence
When TTFB looks slow, use this order. It avoids the common mistake of optimizing application code before confirming cache and routing behavior.
Step 1: Test the main document, not just the whole page
Find the request for the HTML document. Record total TTFB and the timing breakdown. Repeat with and without browser cache. Test a public page, a dynamic page, and a logged-in page if relevant.
Step 2: Compare regions
Run the same URL from several geographic locations. If the slow regions correlate with distance from origin, prioritize CDN and edge caching. If every region is slow, look at backend processing and origin capacity.
Step 3: Inspect response headers
Look for cache headers, cookies, Age, CDN status, and Vary. A missing Age header or repeated cache misses are clues. A broad Vary: Cookie header on public HTML is often a cache killer.
Step 4: Check origin timing
Add server timing instrumentation. The Server-Timing header can expose backend phases such as database time, render time, and upstream API time. Even simple labels are useful:
Server-Timing: db;dur=82, render;dur=41, api;dur=210Now your browser timings can show whether the server spent 300 ms on real work or whether the delay happened before the request reached your application.
Step 5: Fix the largest confirmed delay
This sounds obvious, but teams often fix what is familiar rather than what is measured. If cache misses dominate, fix caching. If the database dominates, fix queries. If TLS and connection setup dominate for global users, fix routing, CDN coverage, or origin geography.
Front-end work still matters. Fonts, images, and JavaScript affect what happens after the HTML arrives. But they are not substitutes for a fast first response. If you are also working through render performance, web fonts remain one of the easiest wins on many sites because they affect how quickly text becomes usable after the document arrives.
Fixes that usually work
Cache public HTML at the edge
For marketing pages, documentation, blogs, landing pages, and category pages, edge caching is often the biggest TTFB improvement. Use short TTLs if content changes frequently. Use stale-while-revalidate if slightly stale content is acceptable while the cache refreshes in the background.
Be careful with personalization. If a page varies by currency, language, login state, or experiment group, define those variants explicitly. Accidental per-user variation destroys cache efficiency.
Move non-critical work out of the request path
Email sending, analytics enrichment, recommendation generation, webhook calls, and heavy logging should rarely block the first byte. Put them in queues or run them after the response is started.
Reduce backend dependency chains
Parallelize independent calls. Cache responses from slow APIs. Set timeouts. Design fallback content for services that are helpful but not essential.
A slow recommendations widget should not delay the entire product page.
Put compute closer to users
If your users are global and your origin is in one region, latency is structural. CDN caching can hide much of this for public content. For dynamic content, consider regional deployments, edge rendering for suitable routes, or moving APIs closer to the audience.
Keep redirects boring
Canonicalize URLs in one hop. Update internal links so users and crawlers go directly to the final destination. Audit old campaign URLs and platform migrations. Redirects are easy to ignore because they are invisible when they work, but they still cost time.
What not to do
Do not chase a perfect TTFB number for every route. An authenticated report that performs real computation will not behave like a cached blog post.
Do not use average TTFB as your only metric. Percentiles matter. Geography matters. Page type matters.
Do not assume a CDN means your HTML is cached. Verify it.
And do not treat TTFB as separate from product decisions. Personalization, experimentation, real-time inventory, and third-party services all have latency costs. Some are worth it. Some are just habit.
<!-- tool-cta:start -->
💡 Try this: When diagnosing TTFB, Get Headers reveals cache status, server timings and redirects that often explain where the delay is coming from.
<!-- tool-cta:end -->
The calm version of the plan
A slow TTFB is usually fixable once you stop treating it as a vague “server problem”. Measure the document request. Segment by region and page type. Inspect headers. Compare client timing with origin timing. Then fix the biggest confirmed bottleneck.
Most sites do not need exotic architecture. They need fewer avoidable cache misses, less blocking backend work, cleaner redirects, and a clearer idea of what must happen before the first byte is sent.
Frequently asked questions
Is TTFB a Core Web Vitals metric?
What is a good TTFB target?
Will adding a CDN automatically fix TTFB?
Can JavaScript optimization improve TTFB?
Why is my TTFB slow only for logged-in users?
Sources & further reading