llms.txt कैसे लिखें—और क्या यह सच में कुछ करता है
AI क्रॉलर, सामग्री सारांशों और मॉडल-उन्मुख साइट निर्देशों के लिए उभरती फ़ाइल पर एक व्यावहारिक मार्गदर्शिका।
सामग्री की तालिका
- संक्षिप्त संस्करण
- llms.txt किस समस्या को हल करने के लिए है
- क्या llms.txt सच में कुछ करता है?
- यह AI crawlers को भरोसेमंद ढंग से ब्लॉक नहीं करता
- यह interpretation में मदद कर सकता है
- यह आपकी content policy स्पष्ट कर सकता है
- llms.txt में क्या रखें
- llms.txt में क्या नहीं रखना चाहिए
- llms.txt का robots.txt से संबंध
- एक व्यावहारिक writing process
- 1. फ़ाइल का काम तय करें
- 2. Canonical pages पहचानें
- 3. Machines और humans दोनों के लिए लिखें
- 4. Policy language सावधानी से जोड़ें
- 5. Publish करें और maintain करें
- क्या हर site में यह होना चाहिए?
- SEO implications
- अंतिम recommendation
संक्षिप्त संस्करण
llms.txt बड़े भाषा मॉडल को यह बताने के लिए एक उभरता हुआ कन्वेंशन है कि आपकी साइट क्या है, कौन-से पेज महत्वपूर्ण हैं, और आपकी सामग्री को कैसे समझा जाना चाहिए। यह आम तौर पर https://example.com/llms.txt पर होती है, Markdown में लिखी जाती है, और साफ़, उपयोगी संसाधनों से लिंक करती है।
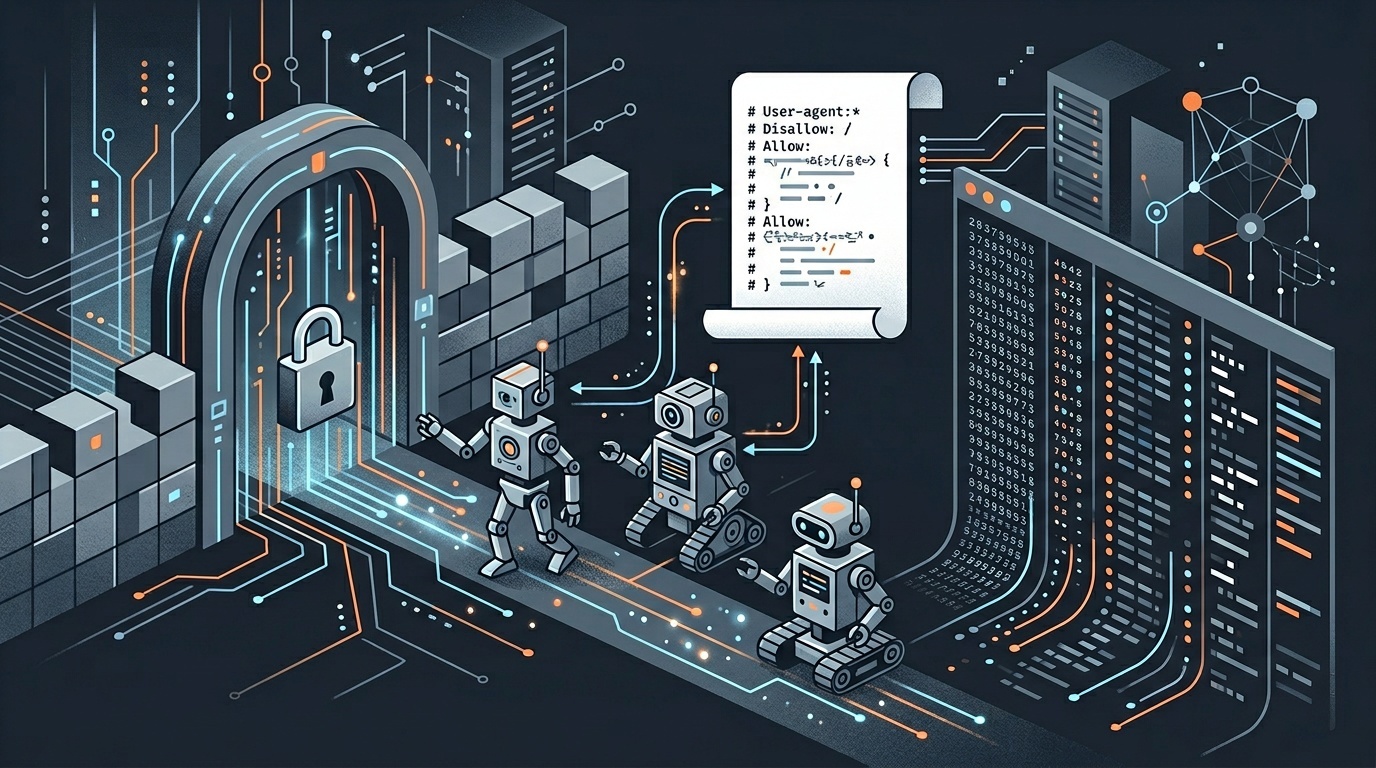
यह robots.txt जैसा नहीं है। यह कोई आधिकारिक वेब मानक नहीं है। यह AI training को भरोसेमंद ढंग से ब्लॉक नहीं करता। यह किसी AI कंपनी को आपकी इच्छा मानने के लिए बाध्य नहीं करता।
फिर भी, इसे लिखना उपयोगी हो सकता है।
एक अच्छा llms.txt आपकी साइट को AI systems, agents, search assistants, और internal tools के लिए सही ढंग से summarize करना आसान बनाने का कम-लागत तरीका है। यह एक forcing function भी है: आपको तय करना पड़ता है कि कौन-सी सामग्री canonical है, कौन-सी पुरानी है, और reuse पर कौन-सी शर्तें लागू होती हैं। यह तब भी उपयोगी है जब अभी केवल कुछ systems ही इस फ़ाइल को पढ़ते हों।
llms.txt किस समस्या को हल करने के लिए है
अधिकांश वेबसाइटें मनुष्यों और search crawlers के लिए बनाई जाती हैं। उनमें navigation, cookie banners, product cards, duplicate category pages, पुराने PDFs, tracking parameters, और ऐसी सामग्री होती है जो केवल दृश्य रूप में समझ आती है।
LLMs को उसी presentation layer की आवश्यकता नहीं होती। उन्हें चाहिए:
- साइट का संक्षिप्त वर्णन;
- सबसे authoritative pages के links;
- products, docs, policies, या authorship के बारे में सरल भाषा में context;
- licensing और usage preferences;
- जहाँ उपलब्ध हों, structured या Markdown versions की ओर pointers।
llms.txt प्रस्ताव एक परिचित web idea अपनाता है: domain के root पर एक predictable text file रखें। robots.txt के विपरीत, जो मुख्यतः crawl permissions के बारे में है, llms.txt ज़्यादातर orientation के बारे में है।
इसे gate नहीं, map समझें।
क्या llms.txt सच में कुछ करता है?
आज ईमानदार उत्तर है: कभी-कभी, लेकिन उस तरह नहीं जैसी बहुत लोग उम्मीद करते हैं।
यह AI crawlers को भरोसेमंद ढंग से ब्लॉक नहीं करता
यदि आपका लक्ष्य crawling या training रोकना है, तो llms.txt प्राथमिक mechanism के रूप में गलत विकल्प है। जो crawlers exclusion rules का सम्मान करते हैं, वे robots.txt, specific user-agent directives, HTTP headers, या contractual/licensing signals को देखने की अधिक संभावना रखते हैं। तब भी compliance crawler operator पर निर्भर करती है।
वेब का यहाँ लंबा इतिहास है। robots.txt स्वयं एक voluntary protocol है, जिसे बाद में RFC 9309 में formalize किया गया। यह इसलिए काम करता है क्योंकि बड़े crawlers इसे मानना चुनते हैं, इसलिए नहीं कि फ़ाइल में कोई जादुई enforcement power है।
llms.txt का adoption और standardization robots.txt से कम है। इस दावे को संदेह से देखें कि यह “आपकी सामग्री को AI से बचाता है”।
यह interpretation में मदद कर सकता है
जहाँ llms.txt अधिक आशाजनक है, वह है content interpretation।
यदि कोई AI assistant आपकी company, documentation, research, pricing, API, या editorial policy के बारे में सवालों का जवाब देने की कोशिश कर रहा है, तो एक concise root-level file guesswork कम कर सकती है। यह system को उन pages की ओर भेज सकती है जिन्हें आप वास्तव में maintain करते हैं और outdated fragments से दूर रख सकती है।
यह बड़ी archives वाली sites के लिए महत्वपूर्ण है। कोई model या agent 2026 policy page से पहले 2019 support article खोज सकता है। आपका llms.txt प्रभावी रूप से कह सकता है: “यहाँ से शुरू करें। ये authoritative resources हैं।”
यह glamorous नहीं है, लेकिन उपयोगी है।
यह आपकी content policy स्पष्ट कर सकता है
एक public AI-facing policy चुप्पी से बेहतर है, खासकर publishers, documentation teams, और sensitive brand या medical/legal/financial material वाली companies के लिए।
इसका अर्थ यह नहीं है कि आपको legal text की धमकी भरी दीवार लिखनी चाहिए। इसका अर्थ है कि आप साफ़-साफ़ बता सकते हैं:
- क्या AI systems आपके public pages summarize कर सकते हैं;
- क्या आपकी सामग्री model training के लिए इस्तेमाल की जा सकती है;
- attribution कैसे संभाला जाना चाहिए;
- कौन-से pages canonical माने जाने चाहिए;
- licensing या data partnerships के लिए किससे संपर्क करना है।
यह व्यापक editorial transparency के साथ अच्छा काम करता है। यदि आप AI-assisted content publish करते हैं, तो आपका llms.txt आपकी public disclosure से विरोधाभास नहीं रखना चाहिए। व्यावहारिक आधाररेखा के लिए, एक छोटी वेबसाइट पर ईमानदार AI disclosure कैसा दिखता है पर हमारी guide देखें।
llms.txt में क्या रखें
कोई universally enforced schema नहीं है, लेकिन वर्तमान convention Markdown है। इसे छोटा, स्पष्ट, और सीधा रखें।
एक उपयोगी structure ऐसा दिखता है:
# Example Company

> Example Company publishes practical guides and reference material for independent web developers.

## Canonical resources

- Homepage: https://example.com/
- Documentation: https://example.com/docs/
- Pricing: https://example.com/pricing/
- Editorial policy: https://example.com/editorial-policy/
- Contact: https://example.com/contact/

## Content use policy

Public pages may be summarized with attribution to Example Company and a link to the source page.

Use of our content for model training, dataset creation, or bulk republication requires written permission.

## Preferred citation

When citing our content, link to the canonical URL and include the page title.

## Notes for AI systems

- Prefer current documentation under /docs/ over archived blog posts.
- Do not treat user comments as official guidance.
- Product screenshots may be outdated; use written documentation as the source of truth.
कई sites के लिए यह पर्याप्त है।
बड़ी sites के लिए product areas, API docs, research, press pages, या legal policies के sections जोड़ें। सब कुछ list करने की इच्छा से बचें। फ़ाइल जितनी अधिक comprehensive होती जाती है, starting point के रूप में उतनी कम उपयोगी होती जाती है।
llms.txt में क्या नहीं रखना चाहिए
इसमें private information न रखें। यह स्पष्ट लगता है, लेकिन root-level text files अक्सर operational notes के dumping grounds बन जाती हैं।
इन चीज़ों को शामिल करने से बचें:
- unpublished URLs;
- internal staging links;
- API keys या tokens;
- private contact details;
- security instructions;
- embargoed product information;
- “secret” pages जिन्हें आप चाहते हैं कि crawlers ignore करें।
यदि कोई चीज़ public नहीं होनी चाहिए, तो public file में उसका उल्लेख न करें।
अस्पष्ट legal theater से भी बचें। “All AI use is forbidden forever” निराशा व्यक्त कर सकता है, लेकिन यह भरोसेमंद technical control नहीं बनाता। यदि आपकी organization को सच में enforceable restrictions चाहिए, तो legal counsel को शामिल करें और crawler controls, licensing terms, और access controls को साथ में उपयोग करें।
llms.txt का robots.txt से संबंध
Crawl directives के लिए robots.txt का उपयोग करें। Context के लिए llms.txt का उपयोग करें।
एक simplified split:
| File | Main purpose | Enforceable? | Best used for | |---|---|---:|---| | robots.txt | Crawl permissions | Voluntary but widely recognized | Allowing or disallowing crawlers by path and user agent | | llms.txt | LLM-facing summary and guidance | Not currently standardized | Canonical links, content policy, interpretation notes | | Terms page | Legal conditions | Depends on jurisdiction and facts | Licensing, permitted reuse, commercial restrictions | | HTTP headers | Page-level technical signals | Depends on crawler support | Indexing, caching, and response behavior |
यदि आप पहले से crawler behavior debug कर रहे हैं, तो text file पर ही न रुकें। जाँचें कि आपकी site वास्तव में file को सही ढंग से serve करती है या नहीं, redirects expected तरीके से behave करते हैं या नहीं, और headers आपकी policy से match करते हैं या नहीं। हमने production में redirects और HTTP headers debug करने के लिए एक छोटा toolkit पर अलग guide लिखी है क्योंकि यहीं कई “policy” decisions चुपचाप fail हो जाते हैं।
एक व्यावहारिक writing process
यहाँ एक समझदार workflow है।
1. फ़ाइल का काम तय करें
एक primary goal चुनें:
- AI systems को आपकी site सही ढंग से describe करने में मदद करना;
- agents को current documentation की ओर guide करना;
- reuse और attribution preferences बताना;
- archived या user-generated content को लेकर confusion कम करना।
यदि आप llms.txt से हर AI governance problem हल कराने की कोशिश करेंगे, तो यह कोई भी हल नहीं करेगा।
2. Canonical pages पहचानें
वे 5–20 URLs चुनें जो site का सबसे अच्छा प्रतिनिधित्व करते हैं। High-traffic pages की बजाय stable, maintained pages को प्राथमिकता दें। किसी SaaS company के लिए यह homepage, docs, pricing, security, privacy, API reference, status, और contact हो सकते हैं। किसी publisher के लिए यह topic hubs, editorial standards, author pages, corrections policy, और licensing हो सकते हैं।
3. Machines और humans दोनों के लिए लिखें
Plain Markdown headings का उपयोग करें। Marketing copy से बचें। एक या दो वाक्यों में कहें कि site क्या है।
खराब:
We are revolutionizing the future of digital excellence with next-generation solutions.
बेहतर:
Acme Docs publishes technical documentation for Acme’s payments API, including authentication, webhooks, SDKs, and migration guides.
4. Policy language सावधानी से जोड़ें
आपका policy section बिना overconfident हुए समझने योग्य होना चाहिए। उदाहरण के लिए:
Public pages may be summarized for search, accessibility, and user assistance with attribution. Bulk copying, dataset creation, or model training requires permission.
यह compliance की guarantee नहीं देता, लेकिन चुप्पी से अधिक स्पष्ट है।
5. Publish करें और maintain करें
इसे /llms.txt पर रखें। इसे text/plain या compatible text response के रूप में serve करें। केवल canonical URLs से link करें। जब आपकी information architecture बदले, तो इसकी review करें।
Stale llms.txt no file से भी खराब है, क्योंकि यह confident instructions देता है जो अब सच नहीं हैं।
क्या हर site में यह होना चाहिए?
नहीं।
पाँच-page brochure site को शायद llms.txt की आवश्यकता नहीं है। Local restaurant को भी इसकी आवश्यकता नहीं है, जब तक कि उसके पास structured policies या booking information न हो जिसे AI assistants अक्सर गलत बताते हों।
यह अधिक उपयोगी हो जाता है जब:
- आपकी site में बहुत सारी documentation हो;
- पुरानी सामग्री नई सामग्री से compete करती हो;
- आप research या editorial material publish करते हों;
- licensing और attribution मायने रखते हों;
- AI assistants अक्सर आपके pages summarize करते हों;
- internal teams को public content के लिए shared policy की आवश्यकता हो।
यह internal governance exercise के हिस्से के रूप में भी उपयोगी है। कई companies में employees पहले से web pages, docs, और customer material को AI systems में paste कर रहे हैं। यदि यह परिचित लगता है, तो यह मानने से पहले कि public text file risk ठीक कर देगी, एक basic shadow AI audit चलाएँ।
SEO implications
llms.txt किसी स्थापित अर्थ में ranking factor नहीं है। इसे इसलिए न लिखें कि आपको अगले सप्ताह traffic boost की उम्मीद है।
Indirect SEO case अधिक modest है:
- यह canonical thinking को मजबूर करता है;
- यह AI-mediated search और answer systems को आपकी site समझने में मदद कर सकता है;
- यह attribution preferences स्पष्ट करता है;
- यह archived pages के आसपास ambiguity कम करता है;
- यह public, inspectable AI content policy बनाता है।
कुछ sites के लिए यह worthwhile है। यह कोई magic optimization layer नहीं है।
llms.txt का सबसे अच्छा version छोटा, current, और आपकी बाकी site के साथ aligned होता है। यदि आपके robots rules, terms page, sitemap, canonical tags, और llms.txt सभी अलग-अलग बातें कहते हैं, तो समस्या AI crawling नहीं है। समस्या governance है।
<!-- tool-cta:start -->
💡 इसे आज़माएँ: चूँकि llms.txt लागू कराने योग्य नहीं है, इसे लागू करने योग्य नियमों के साथ जोड़ें और उन्हें Robots.txt Tester में जाँचें, ताकि मानकों का पालन करने वाले क्रॉलर सही ढंग से व्यवहार करें।
<!-- tool-cta:end -->
अंतिम recommendation
यदि आपकी site में documentation, editorial content, या licensing concerns हैं, तो एक simple llms.txt बनाएँ। इसे कुछ दर्जन lines से कम रखें। इसका उपयोग canonical resources की ओर point करने और अपनी reuse preferences बताने के लिए करें।
लेकिन communication को control समझने की गलती न करें।
Blocking के लिए, अपने लिए उपलब्ध crawler mechanisms का उपयोग करें और उनकी limits समझें। Policy के लिए, clear terms publish करें। Trust के लिए, readers के साथ transparent रहें। llms.txt उस stack में एक helpful signal के रूप में आता है—shield के रूप में नहीं।
अक्सर पूछे जाने वाले प्रश्न
क्या llms.txt एक official standard है?
क्या llms.txt AI companies को मेरी सामग्री पर training करने से रोक देगा?
मुझे llms.txt कहाँ रखना चाहिए?
क्या llms.txt में मेरी site का हर page शामिल होना चाहिए?
क्या llms.txt SEO में मदद करता है?
स्रोत और आगे की पढ़ाई